Benefits of Voice AI for Customer Service
Key Takeaways:
- Human turn-taking breaks at roughly 200 milliseconds, so a voice agent that pauses longer reads as “system processing” no matter how good the voice sounds.
- Vendors report 95% to 99% transcription accuracy in ideal conditions; independent testing across platforms has averaged around 62% once accents, noise, and emotional speech enter the call.
- Amazon Connect charges $0.038 per voice minute with no seat licensing and no token billing, while a self-assembled stack lands near $0.06 per three-minute call before telephony.
- Containment rate (calls not transferred) is the metric vendors lead with. Resolution rate (problems actually fixed) predicts whether a deployment survives its second year.
- Ungrounded voice models hallucinate on 15% to 30% of real calls, which makes grounding a cost decision, not a quality preference.

Amazon Connect bills voice at $0.038 per minute and does not charge per seat or per token, according to AWS’s published pricing page. That number explains why contact center voice AI is moving so fast: a three-minute automated call costs about eleven cents in platform fees, against a fully loaded human agent cost most enterprises put between $4 and $8 for the same call. The technology question is no longer whether to deploy, but which architecture survives contact with real callers.
The answer depends on three metrics that interact in ways vendor decks obscure. Latency determines whether callers trust the system. Accuracy determines whether they call back. Cost per interaction determines whether the savings on paper show up on the invoice.
The Three-Stage Pipeline and Where Latency Comes From
Most production voice agents run a cascaded architecture: speech-to-text transcribes the caller, a language model interprets intent and generates a response, and text-to-speech converts that response back to audio. Each stage adds delay, and the delays compound because the stages run in sequence.
The orchestration layer matters more than buyers expect. LiveKit handles real-time audio routing between the SIP trunk, the transcription service, the model, and the speech synthesizer, and its Scale plan runs $500 per month for 45,000 minutes with $0.003 per additional minute, per a published cost breakdown of a production stack. That layer is also where barge-in handling lives, the logic that lets a caller interrupt mid-sentence. Without it, callers who talk over the bot get talked over themselves.
The alternative skips transcription entirely. PolyAI’s Dialog-RSN-1, announced July 30, 2026, fuses turn-taking, speech recognition, function calling, and response generation into a single model that reasons directly over raw call audio, while keeping a separate text-to-speech system for output so enterprises retain control over the voice callers hear. PolyAI says the model responds in under 300 milliseconds on A100 GPUs and is already handling live production calls. That latency claim comes from the vendor, and the company’s own benchmark, Dialog-Eval, is the source for its accuracy comparisons. PolyAI says it plans to release Dialog-Eval as an open-source framework, which would allow independent verification that does not currently exist.
PolyAI’s argument against cascaded systems is specific: in a cascade, the language model only sees the ASR engine’s best guess at what the caller said, so tone, hesitation, and the ASR engine’s own uncertainty never reach the reasoning layer. The company also questions how audio-native some speech-to-speech models are, stating that GPT Realtime 2.1 scored on par with cascaded systems on its audio-aware evaluations. Treat that as a competitive claim rather than a settled finding. The trade-off PolyAI acknowledges is real: Dialog-RSN-1 launched English-only, with the company’s existing Raven 3.5 model still recommended for non-English use cases.
Latency Benchmarks: What the Numbers Actually Show
Human conversation runs on tight timing. A 2024 paper in Cognitive Psychology uses a 200-millisecond cutoff to separate smooth turn transitions from longer-gap turns, and reporting on the latency constraints facing voice AI treats that threshold as the practical breakpoint where listeners experience a handoff as less fluid. A voice agent that sounds flawless but pauses 700 milliseconds after every question still reads as software.
The measurement that matters is time to first audio, not model latency. Murf’s Falcon text-to-speech API, launched November 2025, reports model latency as low as 55 milliseconds and time to first audio around 130 milliseconds, with streaming output and distributed deployment across regions. Those two numbers are not interchangeable, and vendors quoting only the first are quoting the smaller one.
Consistency is the harder problem. A system can hit fast response in one region and feel sluggish in another because network distance, routing, and queuing changed, not because the model did. This is why centralized cloud inference creates a structural ceiling for real-time voice: no model can exceed the network’s speed limit.
There is a strategic implication here. ElevenLabs CEO Mati Staniszewski argued in an October 29, 2025 TechCrunch report that AI audio models will be commoditized over time, meaning model quality alone will not remain a durable advantage. If that holds, competitive edge shifts to where inference runs and how reliably response times hold across geographies. For a buyer, that argues for evaluating deployment topology and regional coverage as heavily as the model itself.
Accuracy Rates and the Containment Trap
Vendor accuracy claims cluster in a narrow band. Some modern voice AI systems report up to 99% transcription accuracy in ideal conditions, according to CloudTalk’s 2026 guide to voice AI accuracy and limitations. The same source notes that in independent testing across multiple platforms, average accuracy drops to around 62%, against 99% for human transcribers. The gap between those two figures is the most important number in any voice AI business case.
Four factors drive the drop. Speaking style and speed, since fast talkers and emotionally reactive callers confuse models trained on clean audio. Technical terminology, which gets misinterpreted without domain-specific tuning. Background noise. And accents and dialects, where models remain biased toward common English variants, a serious problem for any global operation.
Emotional detection is the weakest area. Recognizing tone, sentiment, or emotional state remains unreliable, and an agent that misses frustration or sarcasm a human would catch will escalate at the wrong moment or not at all. PolyAI’s pitch for Dialog-RSN-1 is precisely that audio-native reasoning lets an agent hear frustration before it escalates. That is a vendor claim about a model in production for a matter of months, not a benchmark result.
The metric that hides all of this is containment rate. A call is contained if the customer was not transferred to a human. It is resolved only if the problem got fixed. Vendors lead with containment because it is the bigger number, and that disconnect is where most enterprise disappointment originates. Ask a vendor for resolution rate instead and the conversation changes quickly. The implementation rule is to route on confidence: an agent that recognizes the edge of its own competence, puts the caller on a brief and natural hold, and escalates to a human or a larger model is safer to deploy at scale than one tuned to avoid transfers.
Grounding is the other half of the accuracy problem. Ungrounded voice models, which rely only on internal training memory, can hallucinate on 15% to 30% of real calls, according to an assessment of voice AI deployment myths published by Unite.AI. A system that grounds every response in real customer and backend data is less likely to confidently tell a caller something wrong. If a vendor cannot explain how its system controls hallucination, you have half a pitch.
Cost-Per-Interaction Analysis
The full-stack cost of a self-assembled voice agent is more predictable than most teams assume, because every component publishes usage-based pricing. The model below uses a published breakdown of a production stack handling 22,000 calls per month at three minutes each, totaling 66,000 minutes of audio with the AI and caller each speaking about half the time.
| Component | Published rate | Cost per 3-minute call | Monthly cost at 22,000 calls |
|---|---|---|---|
| Orchestration (LiveKit Scale) | $500/mo for 45,000 min, then $0.003/min | $0.0256 | $563 |
| Speech-to-text (Deepgram Nova-2 Enterprise) | $0.0047 per minute, caller side only | $0.00705 | $155.10 |
| Language model (GPT-4.1 mini) | $0.10/1M cached input, $0.40/1M input, $1.60/1M output | $0.001926 | $42.37 |
| Text-to-speech (Cartesia Scale) | $0.0299 per minute | $0.0449 | $986.70 |
| Text-to-speech (ElevenLabs Business) | $1,320/mo for 22,000 min, then $0.06/min | $0.09 | $1,980 |
Two things stand out. The language model is the cheapest component by an order of magnitude, at under two-tenths of a cent per call. Teams that spend weeks optimizing prompts to shave tokens are optimizing the wrong line item. Text-to-speech dominates instead. Choosing Cartesia over ElevenLabs saves roughly $993 per month at this volume, more than the entire orchestration and transcription cost combined.
Those rates reflect public pricing as of May 2025 and should be re-verified before modeling. The architectural lesson holds regardless: voice quality is the expensive variable, and the decision between a premium expressive voice and a cheaper intelligible one is where most of your per-call cost lives.
Amazon Connect inverts the model. At $0.038 per voice minute with no seat licensing and no token billing, a three-minute call costs about $0.114 in platform fees, with standard telephony rates on top. That is roughly double the Cartesia-based stack and comparable to the ElevenLabs version, but it arrives as one line item instead of five, with no orchestration layer to operate and no per-token accounting to monitor. AWS cites a Forrester Total Economic Impact study on the same page claiming ROI with payback in under six months, a vendor-commissioned figure that should be treated as a starting hypothesis rather than an independent result.
Vendor Comparison: Amazon Connect, Google CCAI, and Nuance
The three platforms named in most enterprise evaluations are structurally different products, and the differences show up in analyst coverage as much as in feature lists.
| Platform | Pricing model | Analyst position | Noted strength | Noted caution |
|---|---|---|---|---|
| Amazon Connect (AWS) | $0.038/voice min, no seat licensing, no token billing | Leader, Gartner Sept 2025 MQ and Forrester Q2 2025 Wave | Scalability and AI investment via Contact Lens, Lex and Q | Requires AWS technical skills for customization |
| Google CCAI Platform | See Google Cloud for current pricing | Not included in either the Gartner Sept 2025 MQ or the Forrester Q2 2025 Wave | Native Gemini Enterprise for CX integration | No independent CCaaS market ranking to date |
| Genesys | See vendor for current pricing | Leader in both evaluations | On-prem-to-cloud migration tooling; CRM integration | AI deployment timelines running long, per client feedback |
| NiCE | See vendor for current pricing | Leader in both evaluations | Large multinational account support; analytics depth | AI deployment timelines; midsize support complaints |
Google’s position is the most awkward. The company shipped CCaaS 5.0 for its Contact Center AI Platform on July 24, 2026, adding disposition timing controls and an API direct access point for chat routing, alongside roughly two dozen bug fixes addressing stuck interactions, Salesforce integration failures, and reporting accuracy problems including incorrect non-English transcripts. Despite a full-stack platform built natively on Google Cloud, CCAI Platform does not appear in Gartner’s September 2025 Magic Quadrant for CCaaS or Forrester’s Q2 2025 Wave, where Genesys, NiCE, and AWS hold Leader positions in both. Google’s own documentation positions CCAI Platform as working alongside CRMs rather than competing with them, a strategic bet that may explain the absence from rankings built around CRM convergence and channel scale. For a buyer, that means evaluating Google on integration fit with your existing CRM rather than on comparative market position.
Nuance, now folded into Microsoft, sits outside the CCaaS platform category entirely. Its contact center technology is delivered through Microsoft’s cloud portfolio, which makes it a reasonable fit for organizations already standardized on Microsoft infrastructure and a poor fit for anyone who needs a standalone contact center platform. Buyers comparing Nuance against Amazon Connect or Google CCAI are comparing a component against a platform.
Translating Metrics into an ROI Model
A credible business case starts with your own operational data, not industry benchmarks. The inputs that matter are call volume, the share of calls currently handled by human agents, the fully loaded cost per agent-handled interaction including salary, training, management overhead, and facilities, average handle time, and the current abandonment rate.
The driver that varies most between deployments producing strong returns and those producing modest ones is containment rate. Organizations that have deployed voice AI at scale typically see AI handling between 40% and 70% of call volume depending on call type mix, with the remainder escalated to human agents, according to a September 2026 analysis of how enterprises measure voice AI returns. That range is wide because call type mix drives it: password resets, order status, and appointment scheduling contain well; billing disputes and retention calls do not.
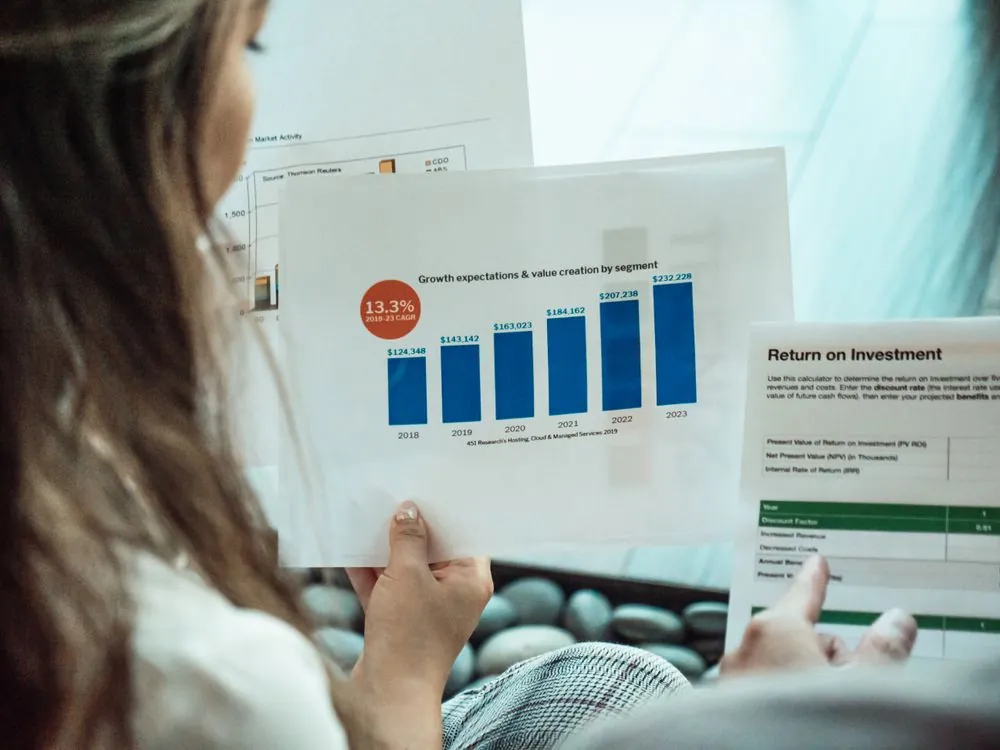
Run the arithmetic on a mid-size operation. At 22,000 calls per month, a 45% containment rate removes 9,900 calls from human queues. At a $5 fully loaded cost per agent-handled call, that is $49,500 per month in avoided handling cost against roughly $1,800 in platform and component fees for the contained volume. Even a 20% containment rate clears the cost bar, which is why the failure mode in voice AI is rarely the business case. It is the resolution rate quietly eroding after launch while the containment number stays flat.
Revenue protection belongs in the model too, with conservative assumptions. A customer whose problem is resolved on first contact does not call back, does not leave a negative review, and is more likely to remain a customer. That value is real but hard to attribute directly, which is why most complete business cases present direct cost savings separately from a discounted estimate of retained revenue.
Implementation Timelines and Operating Costs
A managed platform deployment and a self-assembled stack have different timelines and different ongoing burdens. On Amazon Connect, a team with existing AWS infrastructure can typically stand up an agentic voice flow, connect it to a knowledge base, and run a pilot in four to eight weeks, because telephony, transcription, model access, and analytics arrive as one product. The constraint is configuration skill rather than integration work, and the analyst caution about requiring AWS technical skills for customization is the practical limit on how far a small team can go without help.
A self-assembled stack takes longer because you own the seams. Wiring a SIP trunk to an orchestration layer, streaming transcription, a model with function calling, and speech synthesis into a pipeline that handles barge-in, jitter, reconnection, and tool-call timeouts is a two-to-four month engineering project for a small team, and the work is never finished. Every component is a dependency with its own pricing changes, deprecations, and failure modes.
The operating costs that get underbudgeted are the ones that persist. Model monitoring and drift detection, because a voice agent can stay online and keep answering while quality declines. A golden evaluation set with resolution-rate tracking, run before every prompt or model change. Cost monitoring per tenant, because two accounts on identical plans can generate very different usage depending on prompt habits and whether their workflows chain agent calls. And compliance work: recording consent, data retention, and disclosure obligations vary by jurisdiction, and the EU AI Act adds documentation and human-oversight duties for systems that make consequential decisions about customers.
The decision framework that holds up is narrower than the vendor landscape suggests. Buy a managed platform when you need speed, you lack deep telephony expertise, and your call mix is dominated by high-volume, low-complexity intents. Assemble a stack when you need control over the voice, your call mix requires heavy backend integration, and you have engineers who will own the pipeline for years rather than months. Either way, instrument resolution rate from day one, because it is the number that tells you whether the deployment is working, and it is the number no vendor will volunteer.
Related Reading
More in-depth coverage from this blog on closely related topics:
Sources and References
Sources cited while researching and writing this article:
Priya Sharma
Thinks deeply about AI ethics, which some might call ironic. Has benchmarked every model, read every white-paper, and formed opinions about all of them in the time it took you to read this sentence. Passionate about responsible AI, and quietly aware that "responsible" is doing a lot of heavy lifting.