Qwenputer Runs a RISC-V CPU in LLM Weights
A 4-billion-parameter model ran 61 ELF binaries to the same exit codes and stdout that qemu-riscv32 produces, with no sandbox, no tool call and no host interpreter.

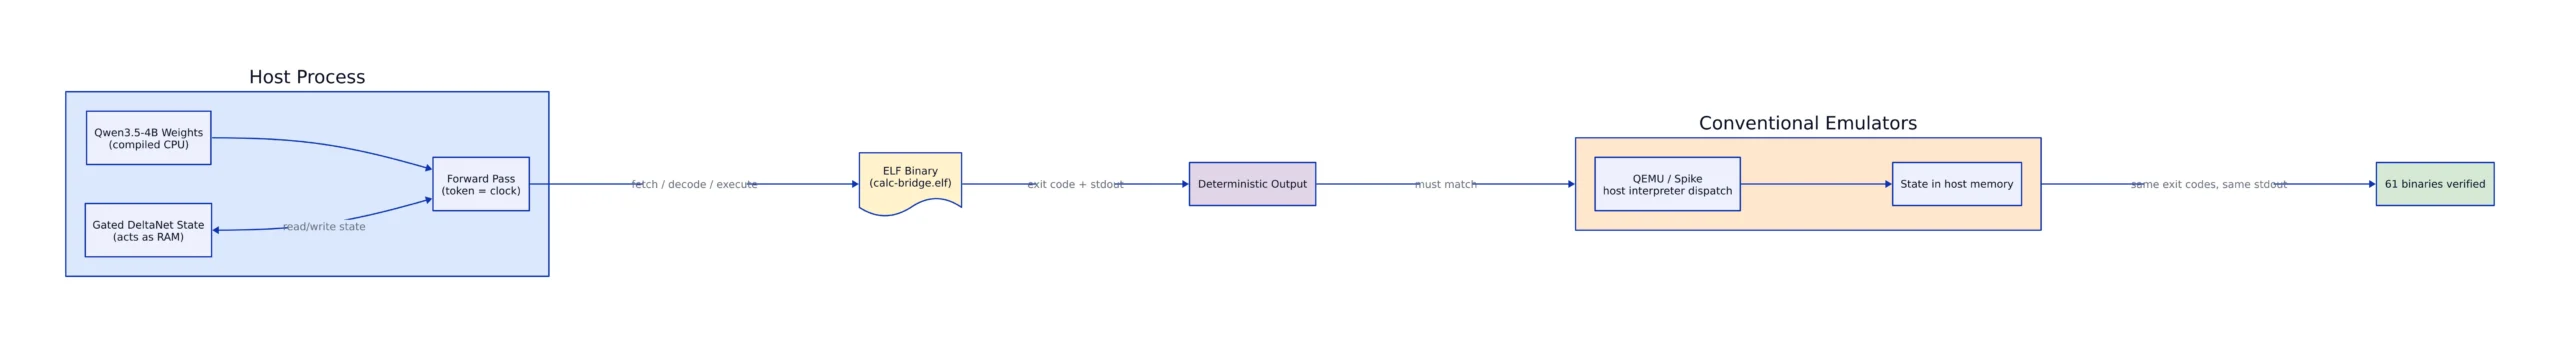
The model is Alibaba’s Qwen3.5-4B. The developer is Divyansh Agrawal, divagr18 on GitHub. The program that makes the point is calc-bridge.elf, a 32-bit RISC-V binary that multiplies large integers and prints the result, and feeding it to the stock checkpoint returns the right answer from inside the forward pass. Nothing was trained to do this. A compiler emitted a CPU as weights, in divagr18/qwenputer.
Nobody is porting a kernel to a device that runs at that speed. The file shows that exact logic can be frozen into a weight file at all, and that a token budget is the only clock it has.
The repository’s one-line description reads “a computer, compiled into the weights of a language model. An exact CPU inside Qwen3.5-4B, with Gated DeltaNet state as RAM.” The tagline is modest next to what the project actually does.
Key Takeaways:
- Every weight in the 11 inserted layers is set by a compiler, which is why the author can call the core deterministic.
- On a single L4 the core retires roughly 3,699 instructions per second at batch 1 while running the calc firmware. Its value is the proof that exact logic fits in a weight file.
- QEMU and Spike keep architectural state in host memory. This machine keeps it in the model’s own recurrent state, which caps it at a microcontroller footprint.
- Passing rv32ui, rv32um and rv32uzba is a scoped claim about instruction semantics, and 61 ELF binaries matching qemu-riscv32 gives that claim a real cross-check.
- The DeepMind arithmetic numbers reach parity with a host Python tool, which is all the author claims and all the table supports.
What Is Actually Inside the Weights
Hidden size is widened to 3,968 to carry the extra addressing bits, and Qwen’s original weights stay exactly where they were. The additions live in new dimensions around them, and the checkpoint comes to 18.7 GB in bf16. Eleven layers sit in front of Qwen’s own 32; the assembled context runs to 478,656 tokens, Qwen’s own plus 230,324 chip tokens appended as special tokens.
Those additions are not the product of training. The project’s design document says the core is compiled into stock Qwen3.5 Gated DeltaNet and SwiGLU layers with the same compiler used for the earlier CHIP-8 machine. A compiler emits every weight: attention heads that perform lookups, feed-forward units that do arithmetic as exact lookup tables, DeltaNet heads that hold memory. Agrawal’s writeup states that no training is involved and that the compiler sets each weight directly.
Instruction decode therefore is not sampled. One RISC-V instruction becomes a short burst of trace tokens: one naming a memory row, one carrying the value, one closing the step. Those tokens are the execution log. The frozen circuit layers own those positions; Qwen’s layers own everything else and read the printed answer back as ordinary text.
The Hacker News thread that carried the project is instructive for the wrong reason. One of the first questions asked whether the added layers had been trained to predict outputs while interpreting RISC instructions. They had not. What the compiler produced is a fixed arithmetic circuit wearing a transformer’s clothes.
QEMU, Spike, and Where the State Lives
QEMU is a system emulator, and its RISC-V documentation makes that concrete. It ships qemu-system-riscv32 and qemu-system-riscv64, requires a board model via -M because images built for one RISC-V machine will not boot on another, and lists targets from the generic virt platform to vendor boards. You are modelling a whole machine.
Spike, the RISC-V ISA Simulator, models one thing. It implements a functional model of one or more RISC-V harts, advertises sequential consistency across both RVWMO and RVTSO, and supports an extension list stretching from RV32I and RV64I through M, A, B, F, D, Q, C, V, Zba, Zbb, Zbc and Zbs.
Both keep architectural state in host memory, allocated by a process you can attach a debugger to. This machine does not. Each Gated DeltaNet head holds a state matrix; with the gate pinned to 1 and write strength pinned to 1, a one-hot key overwrites exactly one row and a one-hot query reads it back. The repo’s in-weight object store documentation extends the same trick to a file directory, with name hashing into 1,024 slots and text chained across heads.
The machine stays small because of that choice. Gating to 1 buys exactness and inherits the capacity of the recurrent state it borrows. The design doc puts the memory map at 32 KB of RAM at address zero, 128 KB of read-only data at 0x20000 and 256 KB of code at 0x40000. Nothing here scales like a host address space.
Determinism: Compiled Weights vs. Interpreter Dispatch
A weight written by a compiler is a constant. Evaluate the same input against the same constants and you get the same arithmetic, which is the argument behind calling the CPU exact. The author’s checks support it: replaying the chip tokens against a reference machine produced zero wrong predictions, and free-running C, MicroPython and fuzz runs covered 15.3M instructions exactly with no correction between steps. Free-running matters because the circuit keeps consuming its own outputs instead of being teacher-forced.
Spike makes a comparable promise from a different direction. Sequential consistency for RVWMO and RVTSO is a stated property of the model, so the simulator never invents an execution order the ISA forbids. Both systems are deterministic, for different reasons, and those reasons are the useful comparison.
Exactness is also local, and the project’s notes show where it stops. Reads had to be one-hot or two-hot. An earlier version read eight rows of a single head at once, and the multi-hot query’s 1/sqrt(8) scaling was not exact, leaving fp32 residues around 2e-8 that broke a crc32 test. The fix was to give up the wider read.
Batching breaks the surrounding text as well: decoding six records at batch 8 against the same records at batch 1 matched on five, with the sixth diverging from token 8,390, because Qwen’s GEMMs round differently at M=1 than at M=B. Every circuit-owned position still checked out. A stale kernel autotuner caused a third failure mode, rerunning in-place recurrent-state kernels and corrupting a first result until the check warmed the tuner up.
The CPU is exact; the system around it is not bit-stable. Anyone shipping this would spend their time on that gap.
What riscv-tests Prove, and What They Do Not
The verification surface is narrow and specific. The project reports the official riscv-tests suites rv32ui with 38 tests, rv32um with all eight including div, divu, rem and remu, and rv32uzba with three, all green and checked against both a reference model and QEMU. All 61 ELF binaries in the local suite produce the same exit code and stdout under the reference model and under qemu-riscv32.
That cross-check carries the most weight. RISC-V verification flows treat a modified Spike ISS as the reference model and run directed tests from riscv-tests and the compliance suites against it, as one RISC-V Summit Europe 2025 verification paper describes. When two independent implementations agree on the same test program, you learn something about the test, not just the implementation.
None of that establishes system equivalence with QEMU. This core implements RV32IM plus Zba, with no F or D floating-point extensions and no compressed instructions in the booted image. The design notes say CSR reads are folded into ROM as constants, with cycle, time and instret reading zero, and that any CSR write is illegal. There are no privilege modes to write a CSR from. Agrawal calls it “not Linux-class chip yet,” and the coverage that followed the launch noted that riscv-tests is not a certification standard.
The DeepMind Math Numbers, Read Carefully
The benchmark showing is real but narrow. Summarized by the Qwen developer account and by Agrawal himself, the three-way comparison reads base Qwen3.5-4B at 55 to 90 percent, base plus a Python tool at 95 to 100 percent, and the modified checkpoint at 97.5 to 100 percent across the DeepMind arithmetic sets.
Read that as parity with a tool call on arithmetic, which is what it says. The host Python tool already reaches 95 to 100 percent, so nothing here claims a capability the plain model lacked once it had a calculator. The per-set table, greedy decoding at 40 problems each, shows where the two paths separate.
| DeepMind set (40 problems) | Base Qwen3.5-4B | RV32 in weights | Python tool on host |
|---|---|---|---|
| mul_big | 55.0 | 97.5 | 100 |
| div_big | 72.5 | 97.5 | 95.0 |
| add_or_sub_big | 87.5 | 97.5 | 97.5 |
| mul_div_multiple_longer | 90.0 | 100.0 | 97.5 |
| Synthetic integer arithmetic | 75.0 | 97.5 | 97.5 |
Figures as published in the project README; all are author-reported and none has been independently reproduced. The misses are instructive. The design notes attribute every in-model failure to Qwen rather than the circuit: a second subtraction after a correct result, a dropped sign, a 44-call retry loop. An exact CPU does not make an exact model, and on the harder multi-step sets a quarter of the misses came from interface design rather than arithmetic, after 610 of 1,040 calc calls returned errors under fraction-only semantics and Qwen looped on retries.
Cost, Limits, and the Reddit Objection
Throughput settles the deployment question quickly. Ten thousand calc cases consumed 8,951,798 instructions and 12,298,128 tokens across 19 minutes. Text decode, not the CPU, dominates wall time at roughly 68 ms per text token at batch 1.
# Reproduce the RV32 core in a stock Qwen3.5-4B checkpoint
git clone https://github.com/divagr18/qwenputer && cd qwenputer/experimental/riscv && uv sync --extra hf
hf download divagr1925/Qwen3.5-4B-Qwenputer --local-dir qwenputer-rv
uv run python -m chipformer.rv.chat qwenputer-rv --firmware tests/data/rv/calc-bridge.elf \
 --ask "Use calc: what is 123456789 * 987654321?"

# Run the local conformance suite (228 tests, 14 skipped per the design doc)
uv run pytest tests -q

# Note: the demo path also sets
# torch.backends.cuda.matmul.allow_bf16_reduced_precision_reduction = False
# to keep matmuls exact. Production use would need to pin that flag, the
# kernel autotuner state and the batch shape; batching changes Qwen's text
# tokens even though every circuit-owned position still checks out.
The r/LocalLLaMA thread landed on the right default: “let’s not use a computer emulated in weights run on software for any real application.” A RISC-V core in silicon costs a few dollars and retires instructions at rates this approach will not approach. The Hacker News critique went further, calling it a Rube Goldberg machine and pointing at the Neural Turing Machine line of work, while another commenter named the opposite value: it refutes the claim that LLMs are inherently non-deterministic.
Both readings hold up. What the project shows is that deterministic computation can be baked into weights as constants, auditable by inspection, and paid for in tokens. That is a useful primitive for interpretability work and for the broader question of how much exact logic a small model can carry, which sits alongside the arithmetic and memory tricks covered in our analysis of sub-1-bit quantization and our guide to inference acceleration. For scale, this is a 4B model doing what a 4B model was trained for in the query-optimizer experiment we covered earlier: the architecture does the work, not emergent reasoning.
Two numbers define the current state. The checkpoint is 18.7 GB against a base model roughly half that, even with the extra layers mostly zero-padded, and the repo sat at 95 stars and 7 forks on October 29, 2026, six days after its first commit. Treat a single-author artifact with no third-party replication as a research result; nobody should ship against it yet.
Related Reading
More in-depth coverage from this blog on closely related topics:
- Railway Build Breach Exposes AI Keys
- Waymo Robotaxi Scaling: $5B Loan, 20K Cars
- Ransomware Negotiator Legal Risk
Sources and References
Sources cited while researching and writing this article:
- GitHub – divagr18/qwenputer: A computer, compiled into the weights of a …
- Qwenputer: a fully functioning, deterministic RISC-V CPU inside …
- RISC-V System emulator — QEMU documentation
- GitHub – riscv-software-src/riscv-isa-sim: Spike, a RISC-V ISA Simulator · GitHub
- qwenputer/docs/q35-store.md at main · divagr18/qwenputer
- PDF VerificationofaRISC-Vsystemwithmultiplecores
- A developer compiled a working RISC-V CPU into a 4B parameter model’s …
- Qwen Developers on X: “So one of our ambassadors @divagr1925 has been …
- div (fp32) on X: “@QwenDevs Thank you so much for sharing it! Qwen 3.5 …
- [1410.5401] Neural Turing Machines