AI inference

Engineer reviewing token usage and API cost dashboards on dual monitors

AI Inference Cost Trends and Economics

Explore how AI inference costs are falling while enterprise bills rise, driven by increased token consumption and model size, shaping AI economics today.

September 23, 2026 9 min read
GPU servers in a data center running large language model inference

How to Speed Up Large Language Models

Discover techniques like weight quantization, KV-cache compression, and speculative decoding to optimize large language model performance and speed up…

September 23, 2026 9 min read
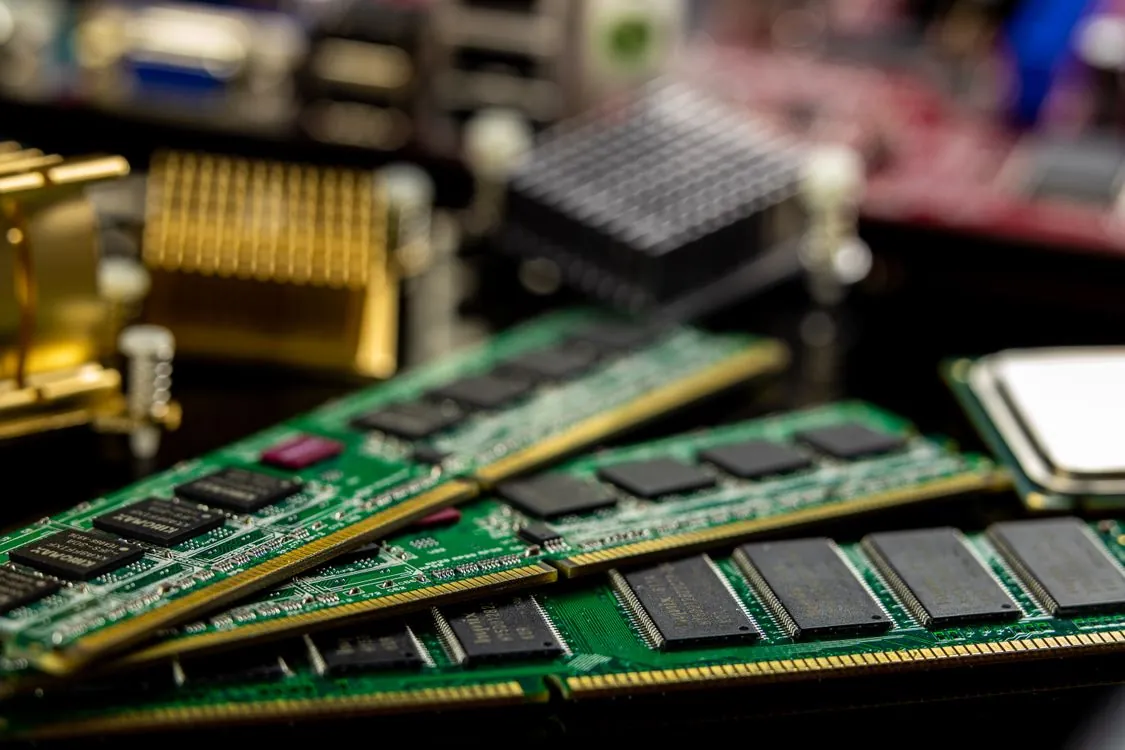
Close-up of processors and memory modules on a motherboard representing the 144-core Fujitsu MONAKA CPU and AI server hardware

Fujitsu Monaka: Next-Gen Japanese CPU

Fujitsu’s Monaka processor launches in November 2026, promising high-performance, air-cooled AI inference with 144 cores, reshaping Japanese semiconductor…

September 17, 2026 11 min read
Analytics dashboard with charts and graphs illustrating perplexity benchmark measurements for quantized language models

Best Quantization Methods for llama.cpp

Discover the best quantization methods for llama.cpp, optimizing performance and accuracy with detailed insights into GGUF formats and hardware considerations.

September 14, 2026 7 min read
Slim aluminum laptop on a desk, representing an Apple Silicon MacBook running local language models

Using Apple Silicon for AI Inference

Explore the capabilities and limitations of Apple Silicon for large language models, comparing it with GPU-based solutions for AI inference workloads.

September 14, 2026 11 min read
Server racks in a data center running AI inference workloads

AI Inference Cost and Model Size Impact

Explore how AI inference costs are declining rapidly, the impact of model size on expenses, and what this means for the future of AI deployment and innovation.

August 26, 2026 9 min read
Server racks representing AI inference infrastructure costs in 2026

AI Inference Cost Trends in 2026

Explore the latest trends in AI inference costs, provider pricing strategies, caching efficiencies, and infrastructure innovations shaping the AI landscape…

August 4, 2026 16 min read
Close-up of server racks representing AI inference workloads, GPU hardware, and rising product infrastructure costs in 2026

AI Inference Costs in 2026: The Inference

Analyze how AI token serving costs are decreasing in 2026, impacting product design, infrastructure, and budgeting strategies across the industry.

July 13, 2026 13 min read
Close-up of server racks in a data center representing AI inference engine architecture and hardware tradeoffs

2026 Comparison of Local AI Inference Engines

Explore the latest in local AI inference engines for 2026, including architecture, benchmarks, security updates, and deployment strategies for optimal…

July 9, 2026 21 min read
Developer working on a laptop running local AI inference with code editor visible

llama.cpp vs vLLM vs SGLang vs Ollama (2026)

llama.cpp vs vLLM vs SGLang vs Ollama in 2026: which local LLM inference engine to run for speed, VRAM, quantization, and serving — with benchmarks and a decision guide.

June 19, 2026 16 min read
Abstract digital light burst with neon blue and purple fiber optic glow representing high-speed data transfer and token processing

A Fully Digital Transformer Chip at 80 MHz

Explore the groundbreaking digital silicon Transformer chip claiming 56,000 tokens/sec at 80 MHz, analyzing feasibility, design principles, and industry…

June 17, 2026 13 min read